英伟达发布Nemotron 3.5 Transcribe开放权重语音模型:可转写40种语言,同步开放46.3万小时语音数据清单
英伟达(NVIDIA)10月28日发布开放权重语音模型 Nemotron 3.5 Transcribe,把多语言转写、说话人标注、翻译与音频问答整合在同一个模型权重中;同时发布的 Granary v2 是开放语音数据集与数据整理管线,其公开清单覆盖48种语言、共463,062小时音频。
据英伟达的发布说明,该模型可转写40种语言,可在其中31种语言与英语之间互译,可对13种语言做说话人标注;可处理最长一小时的录音,一次最多标注八位说话人。模型采用340亿参数混合专家架构(30B-A4B,解码时约激活43亿参数),提供 BF16、FP8 与 NVFP4 三种量化权重。
英伟达称,该模型在 Hugging Face 的 Open ASR 英语排行榜上以5.33%的平均词错率位居开放权重模型第一,在 Artificial Analysis 语音转文字评测中以2.8%的词错率与最佳开放权重模型并列第一。
模型权重以 OpenMDW-1.1 许可证开放,可商用与非商用使用,已上架 Hugging Face、GitHub(NVIDIA NeMo Speech)、NGC 与 build.nvidia.com;Baseten、DeepInfra 与 Simplismart 提供托管推理接口,Hugging Face Spaces 与 ModelScope Studios 有交互演示。
此次发布的是语音转写专用模型,与英伟达此前发布的 Nemotron 系列多模态智能体模型分属不同产品。语音转写是超级智能(SI)应用落地的常用环节,会议记录、客服通话与媒体字幕均为主要应用场景。
NVIDIA Releases Nemotron 3.5 Transcribe Open-Weight Speech Model: Transcribes 40 Languages, With a 463,062-Hour Audio Dataset
NVIDIA released Nemotron 3.5 Transcribe on October 28, an open-weight speech model that combines multilingual transcription, speaker attribution, translation, and audio question answering in a single checkpoint. Alongside it, the company released Granary v2, an open speech dataset and curation pipeline whose public manifest covers 463,062 hours of audio across 48 languages.
According to NVIDIA's announcement, the model transcribes 40 languages, translates 31 of them to or from English, and attributes speakers in 13 languages; it handles recordings up to one hour long and labels up to eight speakers. The model uses a 34-billion-parameter hybrid mixture-of-experts decoder (30B-A4B) that activates roughly 4.3 billion parameters per token, and ships in BF16, FP8, and NVFP4 quantized weights.
NVIDIA says the model ranks first among open-weight models on the Hugging Face Open ASR English Leaderboard with a 5.33% average word error rate, and ties for first among open-weight models on Artificial Analysis Speech-to-Text at 2.8%.
The weights are released under the OpenMDW-1.1 license for commercial or non-commercial use, and are available via Hugging Face, GitHub through NVIDIA NeMo Speech, NGC, and build.nvidia.com. Hosted endpoints are offered by Baseten, DeepInfra, and Simplismart, with interactive demos on Hugging Face Spaces and ModelScope Studios.
The release is a speech-specific model, distinct from NVIDIA's earlier Nemotron multimodal agent models. Speech transcription is a common building block for super intelligence (SI) applications, including meeting notes, customer-service calls, and media captioning.
来源:GSM·美国(原文链接)
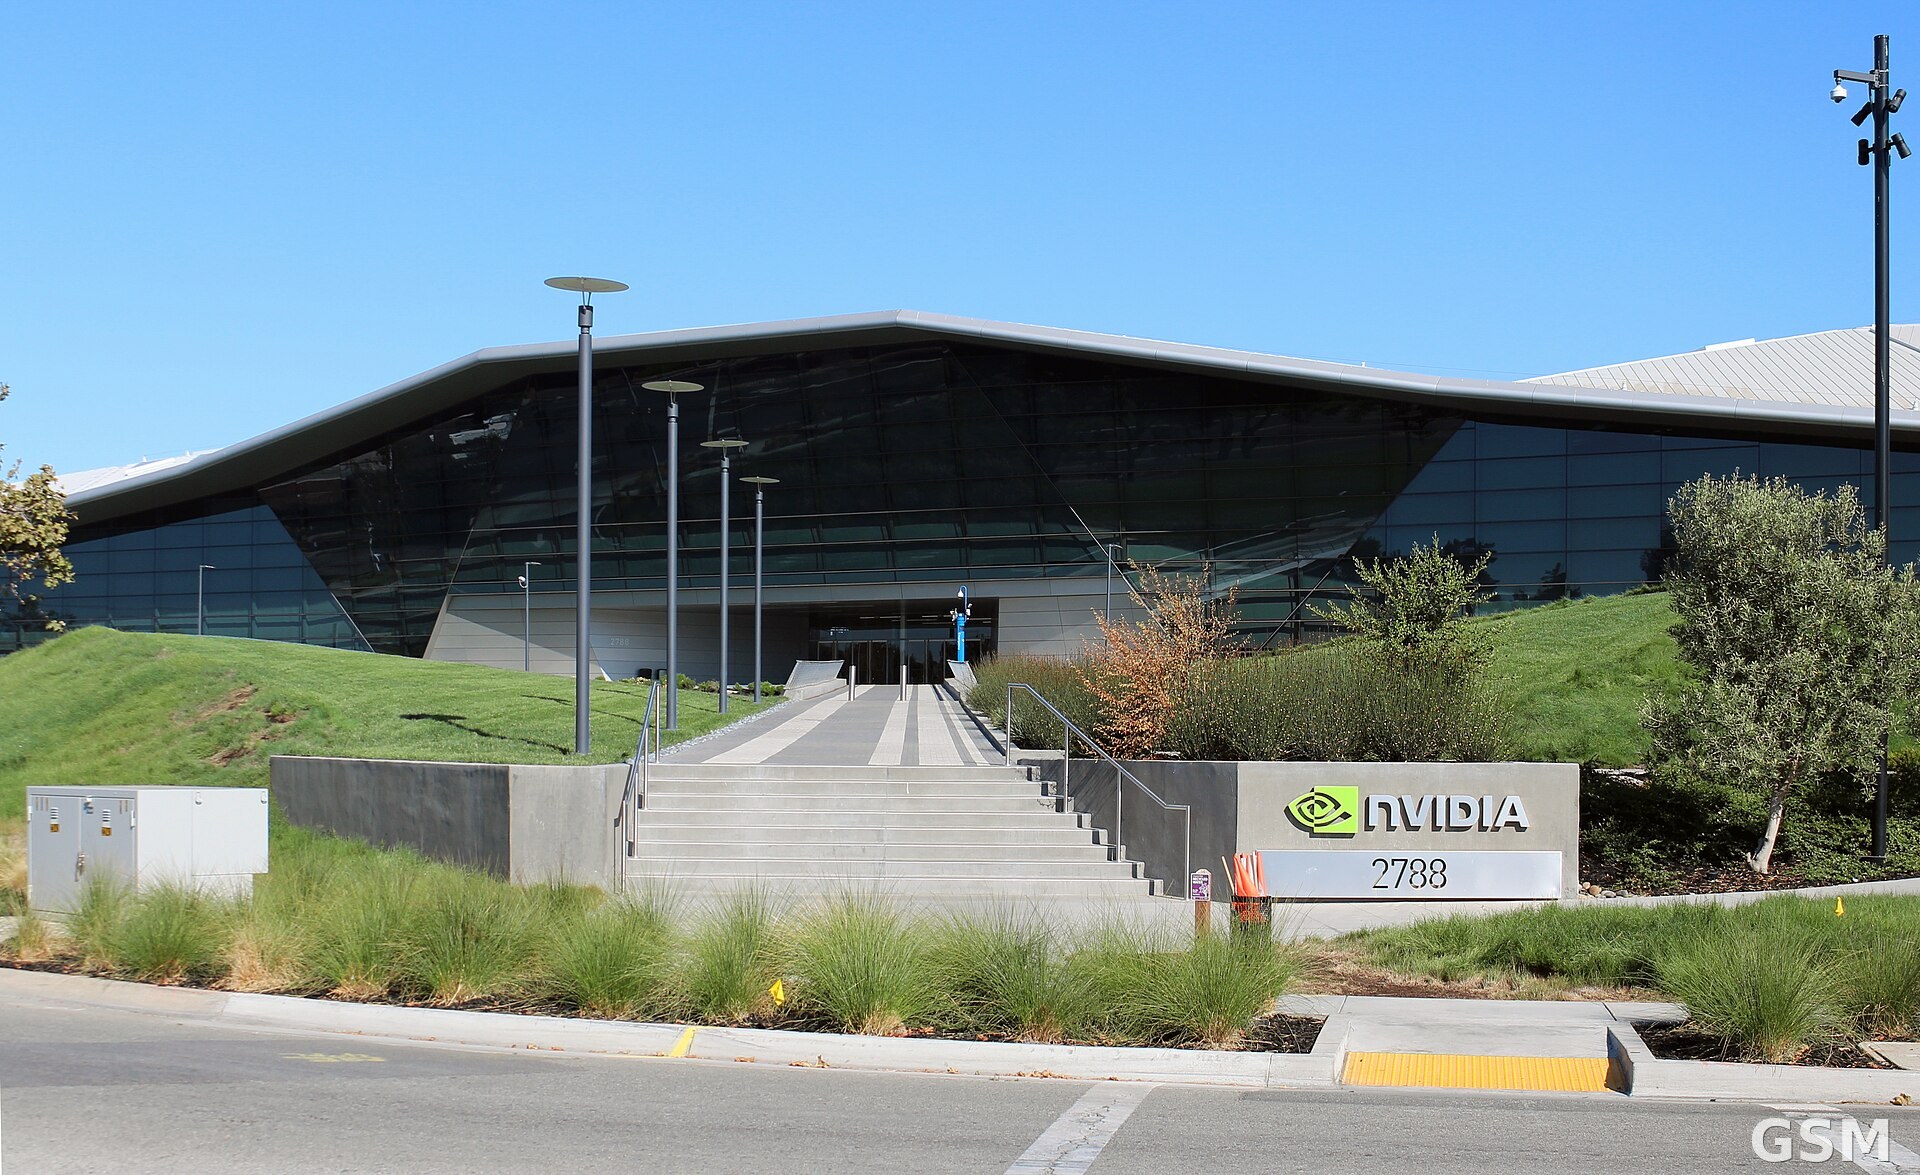
图片来源:图:英伟达位于加利福尼亚州圣克拉拉的总部大楼。CC BY-SA 4.0,经 Wikimedia Commons。 / Photo: NVIDIA headquarters in Santa Clara, California. CC BY-SA 4.0, via Wikimedia Commons.